

To tell whether ChatGPT is down, check the OpenAI status page first. It shows current incidents, links to incident history, and a summary of service areas such as APIs, ChatGPT, Codex, and FedRAMP.[1][2] If it lists an active ChatGPT incident, such as degraded performance, elevated errors, or a partial outage, the problem is on OpenAI’s side and the right move is to wait for recovery updates. If it shows no incident, compare it with user-report signals such as Downdetector, which flags report volume that is significantly higher than normal for that time of day,[17] then test another browser, device, and network. The status page also carries an important disclaimer: availability metrics are reported at an aggregate level across tiers, models, and error types, so your own experience can differ based on the plan and features you use.[1] This guide explains what the openai status page tells you, what it does not tell you, and what to check next when something breaks.
What the OpenAI status page shows
The public status page is built for fast triage. You open it and look for two things: whether OpenAI reports an active incident, and which product area is affected. OpenAI’s public page shows separate service groupings for APIs, ChatGPT, Codex, and FedRAMP, along with a history view for past incidents.[1][2] If you want the short version, the page answers one immediate question well: is this just me, or is OpenAI already tracking a broader problem.
The page also includes a “Subscribe to updates” option, and OpenAI’s Help Center says related notifications for status changes can be received by people who subscribe from that page.[1][6] That is useful if your team depends on OpenAI services during working hours and you do not want to keep refreshing the site manually.
The most important fine print is easy to miss. OpenAI says the availability metrics on the page are aggregated across all tiers, models, and error types, and that individual customer availability may vary depending on subscription tier and the specific model or API feature in use.[1] In plain English, a green status page does not guarantee that your exact workflow is healthy.
| Tool | Who it is for | What it tells you best | Access |
|---|---|---|---|
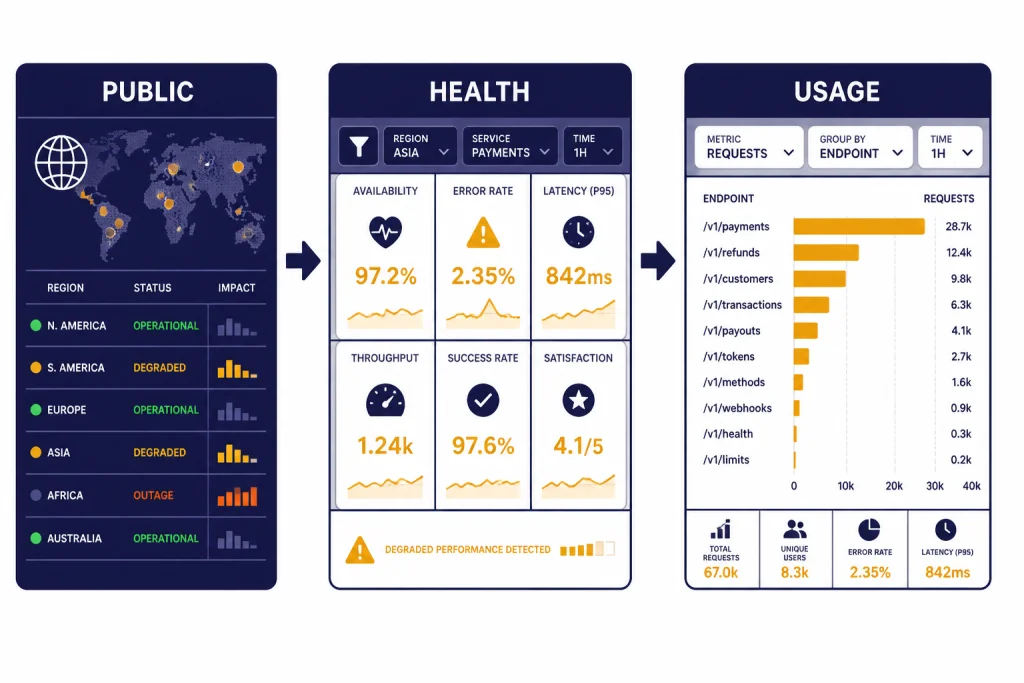
| OpenAI status page | Anyone | Current public incidents, affected product area, incident history, and broad service state.[1][2] | Public.[1] |
| Service Health dashboard | API teams that need deeper debugging | Model-, tier-, and project-level service analysis for troubleshooting API errors and latency.[7] | OpenAI says it is currently available only to Enterprise API customers.[7] |
| Usage dashboard | Org owners and permitted users | Cost, usage, and traffic patterns that help explain whether a spike is tied to your own requests or workload mix.[8] | OpenAI says only organization owners or users with Usage Dashboard permission can access it.[8] |
That distinction matters if you are comparing the public page with your own logs. A consumer checking ChatGPT may only need the openai status page breakdown in principle, but a developer running production traffic often needs the public page plus OpenAI API Errors, openai api pricing, and sometimes azure openai service vs openai api to understand where responsibility actually sits.
How to read an incident update
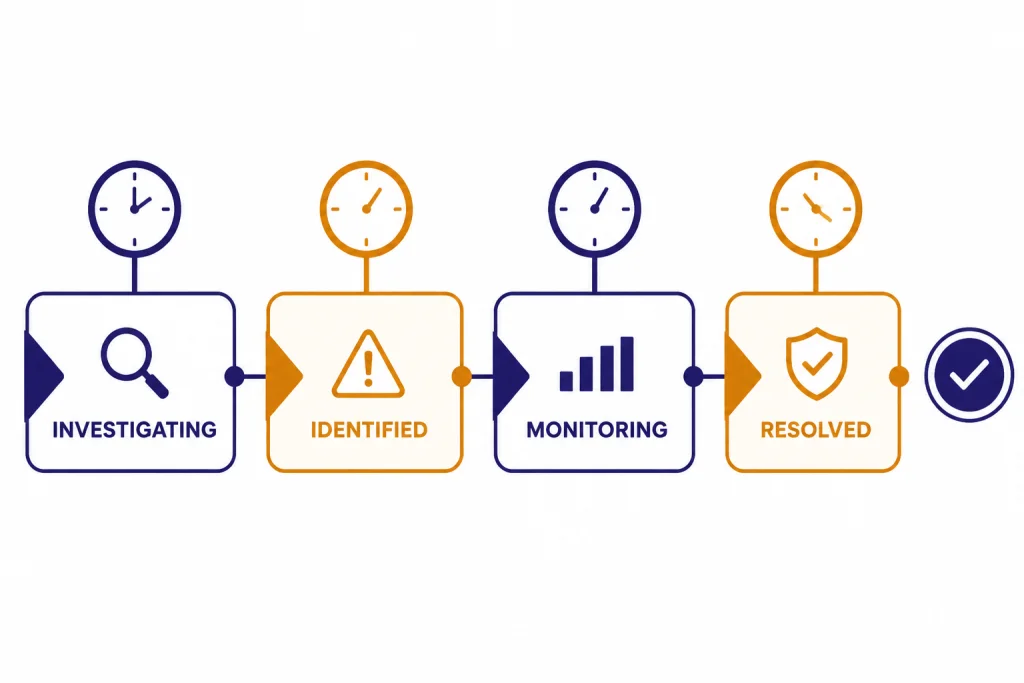
When OpenAI posts an incident, the useful signal is not just the headline. It is the sequence of updates. A typical incident page shows a progression such as Investigating, Identified, Monitoring, and Resolved.[3][4] That sequence tells you how confident OpenAI is about the cause and whether a fix is already in place.

A concrete example helps. On April 14, 2026, OpenAI posted an incident titled “Elevated 401 errors for API endpoints.” The incident page shows the issue moved from identification of intermittent 401s caused by timeouts, to mitigation, to monitoring, and then to resolution on April 14, 2026.[3] On April 6, 2026, OpenAI also logged a separate incident where the GET /v1/responses endpoint was down and unable to serve requests before later reporting full recovery.[4]
Those examples show why the incident timeline matters more than the badge color alone. “Investigating” means you should expect uncertainty. “Identified” usually means OpenAI has narrowed the fault domain. “Monitoring” means a change has been rolled out but OpenAI is still watching recovery. “Resolved” means the issue is considered closed, but your own retries, client caches, or stuck sessions may still need cleanup.[3][4]
If you follow OpenAI News, you already know product rollouts can change how traffic is distributed across models and tools. Incident pages give you the operational side of that story. They are the closest thing to a public maintenance log that OpenAI offers on an ongoing basis.[2]
What OpenAI status terms mean
Status pages use broad labels. They are useful, but they do not always map perfectly to what one user sees. A partial outage can affect one feature, one region, one plan type, one model, or one surface such as the browser app. A degraded-performance notice can mean ChatGPT loads but feels slow. Elevated errors can mean some prompts fail while others work.
| Status signal | What it usually means | What you should do |
|---|---|---|
| Operational | No confirmed broad issue is listed. | Test browser, app, VPN, cookies, extensions, and network. |
| Degraded performance | ChatGPT may work, but responses, login, uploads, or tools may be slow. | Save work locally, retry later, and avoid repeated refresh loops. |
| Elevated errors | Some requests are failing more than usual. | Retry after a pause and start a new chat if one thread is stuck. |
| Partial outage | A subset of ChatGPT users or features is affected. | Check whether your exact feature is named in the incident. |
| Resolved | OpenAI says impacted services have recovered. | Reload, sign out and back in, then retry the original action. |
OpenAI’s history page is important because it shows feature-level incidents, not just broad platform status. Recent examples in the history feed include access problems, login errors, conversation errors, file upload failures, file download failures, and VPN access issues.[2] Those are different problems with different fixes.
Recent ChatGPT incidents to compare against
Past incidents help you recognize the pattern. They also show why a simple yes or no answer can be misleading.
| Incident | What users saw | OpenAI status | Takeaway |
|---|---|---|---|
| January 26, 2026 | Free and logged-out users saw elevated errors. | OpenAI marked ChatGPT availability degraded for free and logged-out users and later resolved it.[10] | Plan and login state can change who is affected. |
| February 3, 2026 | Login and conversation availability were affected across ChatGPT plan types. | OpenAI said a configuration change caused elevated error rates, with full recovery completed at 3:05 PM PST.[11] | Retry storms can slow recovery during a service-side issue. |
| February 4, 2026 | Some users saw 403 errors when accessing ChatGPT. | OpenAI said the issue occurred between 9:06 AM and 9:59 AM PT after a database capacity reduction during cloud maintenance.[12] | An access-looking error can still come from backend capacity trouble. |
| February 12, 2026 | Conversation requests failed for some users. | OpenAI said a deployment issue caused elevated conversation error rates between 1:20 PM and 1:40 PM PST.[13] | Short deployment-related failures may resolve before many users finish troubleshooting. |
| February 26, 2026 | Some ChatGPT apps had elevated errors. | OpenAI marked the issue as a partial outage and resolved it at 3:57 PM.[14] | App-specific incidents can spare the web experience. |
For a longer record, use our ChatGPT outage history. That page is better when you want patterns.
What to do when ChatGPT seems down
If ChatGPT is slow, stuck on an endless spinner, or throwing a generic error, OpenAI’s own Help Center repeatedly points users to the status page before deeper troubleshooting.[5][9] That is the right first move because it prevents wasted effort. If the platform is having a real incident, clearing cookies or switching browsers will not fix the root cause.
- Check the public status page for a current ChatGPT incident.[1][5]
- If nothing is posted, refresh the chat or app session and try a new conversation.[5]
- Disable VPNs, proxies, or browser extensions that can interfere with loading or websockets.[5][9]
- Try an incognito window, a different browser, device, or network.[5][9]
- If the issue persists across devices and networks while the status page still looks normal, collect details and contact support.[5]
This sequence matters because many ChatGPT failures are local even when they feel global. OpenAI’s troubleshooting guidance lists browser cache, extensions, VPNs, secure DNS tools, and network configuration as common causes for errors like “Something went wrong,” websocket failures, or a chat that never finishes loading.[5][9]
For everyday users, the clean rule is simple. If the status page reports an active ChatGPT issue, wait. If it does not, test another network and browser before assuming OpenAI is down. That saves time and avoids false alarms in team chats.
Do not make destructive changes while OpenAI is working on a confirmed incident. Do not delete your account, reset important settings, or repeatedly submit the same high-value prompt without saving it elsewhere. If you are near a deadline, copy your prompt and source material into a local document, then try a lightweight workaround: a new chat, a shorter prompt, the web app instead of mobile, or mobile data instead of Wi-Fi.
If you use paid ChatGPT plans, it also helps to separate service health from account or billing questions. A plan issue is not always a platform outage. Readers comparing plan value can look at chatgpt plus price in 2026, while those tracing account access problems may want OpenAI History for broader company context and product change timelines.
When only one ChatGPT feature is broken
ChatGPT can be partly down. The main chat box may work while files, images, voice, login, connectors, or conversation history fail. OpenAI Status may list affected components, but your first clue is often the feature that breaks.
- Files fail to upload or download. Start with our ChatGPT file upload not working guide. OpenAI also notes that generated files expire quickly and that file download failures can require checking Code Interpreter settings in custom GPTs.[5]
- Images fail but text works. Use the ChatGPT image generator not working checklist before assuming a global outage.
- Voice mode fails. Check microphone permissions, app version, Bluetooth routing, and service status. Then use our ChatGPT voice mode not working guide.
- Code Interpreter expires. Session expiration is not always an outage. See Code Interpreter session expired for recovery steps.
- ChatGPT is slow but not failing. OpenAI says peak-hour patterns can affect response time and recommends checking the status page, clearing cache and cookies, trying another browser, and collecting diagnostics if the issue persists.[15] Our broader slowdown guide is Why Is My ChatGPT So Slow?
Feature-specific problems are common during partial incidents. For example, an outage may affect conversation creation but not the home page, or login but not users who already have a valid session. That is why a single successful test does not prove ChatGPT is fully healthy.
What to collect before contacting support
Do not contact support during a confirmed outage unless you have a billing, account, or data-loss concern. Support cannot restore a service-wide incident for one account. Wait for the official status update, then retry after recovery.
If the problem persists across browsers, devices, and networks after OpenAI Status shows no active incident, OpenAI recommends collecting a HAR file, browser console errors with timestamps, the model used, and the conversation URL or ID before contacting support.[5] For login-specific problems, OpenAI recommends checking the sign-in method, trying incognito, using a different device or browser, turning off VPN, and waiting up to 1 hour after multiple failed login attempts.[16]

What API developers should check next
For API users, the public status page is only step one. OpenAI’s API troubleshooting guidance says meaningful investigation requires filtering by model, service tier, and project in the Service Health dashboard.[7] OpenAI also says the Service Health dashboard is currently limited to Enterprise API customers.[7]
That is an important distinction for smaller teams. If you do not have Enterprise API access, you may only have the public status page plus your own logs. In that case, compare timestamps from your failures against the public incident history, then check whether the failing requests share a model, endpoint, region, or deployment path.[2][3][4]
OpenAI’s guidance also says the Usage dashboard helps explain whether latency changed because your own traffic, tokens, or usage patterns changed.[7][8] That is why a normal-looking status page can still line up with a bad day in your application. Your prompt size may have grown. Your project mix may have shifted. Your timeout setting may be too aggressive. Or your upstream network may be dropping requests before they reach OpenAI at all.[7]
In practice, an API team should work through four layers in order:
- Public incident check on the OpenAI status page.[1][2]
- Your request logs, keyed by endpoint, model, and error class.
- Service Health filters for model, tier, and project, if your organization has access.[7]
- Usage trends to see whether traffic shape changed around the same time.[8]
That approach is more reliable than staring at one dashboard in isolation. It also pairs well with our guides to openai playground, openai agents sdk, and openai agent builder if your failures are tied to a specific workflow rather than the base API itself.
When you contact support about API problems, include the impacted organization IDs, endpoints, and models. OpenAI’s API troubleshooting guidance lists those details as important support context.[7] Also include request timestamps, status codes, request IDs where available, service tier, project, retry behavior, and whether failures appear in OpenAI dashboards or only in your client logs.
Limits of the status page
The public status page is useful, but it is not a complete observability tool. OpenAI explicitly says the reported availability is aggregated and that individual customer availability can vary by subscription tier and specific feature use.[1] That means three common gaps show up in real life.

- Feature-specific failures may not look dramatic on the public page. A narrow problem with one model, one endpoint, or one region can still hurt your workflow before it becomes a broad public incident.[3][4]
- Your own network can mimic an OpenAI outage. OpenAI’s network troubleshooting guidance says VPNs, proxies, filtering tools, and blocked domains can break ChatGPT access even when the platform itself is healthy.[9]
- Public health is not the same as customer health. Enterprise API customers may need the deeper Service Health view to troubleshoot what the public page smooths over.[7]
So the right way to use the openai status page is as a front door, not a final answer. It is excellent for confirming widespread incidents, checking whether OpenAI has acknowledged a problem, and reviewing recent history.[1][2] It is weaker at answering whether your exact organization, model mix, or corporate network is the cause.
That balance is normal. Public status pages are meant to communicate, not to replace internal telemetry. If you keep that in mind, the page becomes much more useful.
For broader company context, you can also read openai’s cto and leadership team, openai and microsoft, and who owns openai? ownership structure explained. Those pieces will not help you fix an outage, but they do explain how OpenAI’s products, infrastructure relationships, and governance fit together.
Official status versus user reports
OpenAI Status and crowd-report sites answer different questions. OpenAI Status answers whether OpenAI has confirmed a service incident. User-report sites answer whether many users are reporting trouble at the same time. Your own test answers whether the problem follows your account, browser, device, or network.
Downdetector shows where user reports are concentrated over the past 24 hours and says it reports incidents when reports are significantly higher than typical volume for that time of day.[17] This is useful early in an outage, before an official incident is posted. It is not proof by itself.
| Signal | Best use | Limit | What to do next |
|---|---|---|---|
| OpenAI Status | Confirmed ChatGPT incidents, recovery updates, affected components | Aggregate reporting can hide account-level or feature-level differences | Wait, retry later, and avoid repeated refresh loops |
| Downdetector or similar reports | Early warning when many users see the same failure | User reports can spike from local ISP, region, or confusion | Compare with OpenAI Status and test another network |
| Your own browser/app test | Finding cache, cookie, VPN, extension, or device problems | Cannot prove a wider outage | Use private browsing, another browser, another device, or mobile data |
| Social posts | Fast anecdotal confirmation during a noisy outage | Unverified and often regional | Use only as supporting context |
Use this rule of thumb. If OpenAI Status confirms an incident and user reports are rising, ChatGPT is probably down or degraded for a meaningful group of users. If OpenAI Status is clean and reports are flat, your next stop should be local fixes. If the evidence conflicts, assume a partial or regional disruption until your own tests prove otherwise.
What common ChatGPT errors mean
Error wording matters. A generic page failure, a login loop, a server code, and a rate-limit warning point to different fixes.
| What you see | Likely meaning | First fix | Related guide |
|---|---|---|---|
| Something went wrong | Generic failure. It may be local or server-side. | Refresh, start a new chat, check status, then test private browsing. | ChatGPT something went wrong error |
| Network error | Your device may not be keeping a stable connection to ChatGPT. | Switch networks, disable VPN or proxy, and retry in another browser. | ChatGPT network error fixes |
| Login failed | Authentication, cookies, provider mismatch, or temporary restriction. | Use the same sign-in method, clear cookies, and try a desktop browser. | ChatGPT login failed |
| 429 Too Many Requests | The client has sent too many requests in a given amount of time; MDN calls this rate limiting.[18] | Stop retrying, wait, and reduce repeated requests. | ChatGPT Error 429 Too Many Requests |
| 500 Internal Server Error | The server hit an unexpected condition that prevented it from fulfilling the request.[19] | Retry later and check for an active incident. | ChatGPT error 500 internal server |
| 502 Bad Gateway | A gateway or proxy received an invalid response from an upstream server.[19] | Refresh after a short pause and check status. | ChatGPT Error 502 Bad Gateway |
| 503 Service Unavailable | The server is temporarily unable to handle the request because of overload or maintenance.[19] | Wait instead of repeatedly reloading. | ChatGPT error 503 service unavailable |
Repeated clicking can make some problems worse. During the February 3, 2026 disruption, OpenAI said increased retry traffic amplified downstream load and slowed recovery in one region.[11] If ChatGPT is already failing, give it a short break before trying again.
Monitoring ChatGPT status for teams
Teams should treat ChatGPT status as an operational signal, not a casual browser check. Assign one owner to watch the status page during incidents. Keep a short internal note with the start time, affected users, affected feature, plan or workspace, browser or app version, network, and exact error text.
For company networks, OpenAI’s network guidance notes that some ChatGPT and Codex features use secure WebSocket connections in addition to standard HTTPS, and that organizations should allow WebSocket traffic over TCP port 443 with the standard upgrade handshake.[9]
That means a team can see three different results at the same time: ChatGPT works at home, fails on company Wi-Fi, and works again on a mobile hotspot. In that case, the public status page may be correct, but your enterprise security stack is still blocking part of the app.
A practical team monitoring checklist:
- Create an internal incident note when multiple people report the same symptom.
- Record the first report time and the last successful use time.
- Check the official status page and history page.[1][2]
- Test one affected account on a different network.
- Test one unaffected account on the affected network, if policy allows.
- Ask IT to review domain allowlists, WebSocket support, TLS inspection, and firewall logs.[9]
- Tell users whether to wait, switch networks, use the web app, use the mobile app, or pause affected workflows.
Frequently asked questions
Is the OpenAI status page public?
Yes. The main status page and the incident history page are publicly accessible.[1][2] You do not need an API key or ChatGPT subscription just to see whether OpenAI has posted an outage.
Does a green status page mean OpenAI is definitely not the problem?
No. OpenAI says its availability metrics are aggregated across tiers, models, and error types, and that individual customer availability may vary.[1] A local network problem, a model-specific issue, or a narrow endpoint failure can still affect you.
What should I do first if ChatGPT is failing?
Check the status page first, then try a refresh, another browser, and another network if no public incident is listed.[5][9] OpenAI’s own help articles recommend that order because many apparent outages are actually local browser or network issues.[5]
What if the API is failing but the status page looks normal?
Compare your request logs with the incident history, then use Service Health and Usage dashboards if your organization has access.[2][7][8] OpenAI says Service Health is currently only available to Enterprise API customers.[7]
Can I subscribe to OpenAI outage updates?
Yes. The public page includes a subscribe option, and OpenAI’s Help Center says people can receive related notifications for status changes by subscribing from the page.[1][6]
Where can I see older OpenAI incidents?
Use the history view linked from the main status page.[1][2] It lists past incidents by date and lets you open individual incident pages for the timeline and affected components.
Does a spike on Downdetector prove ChatGPT is down?
No. It proves that user reports are elevated, not that OpenAI has confirmed an outage. Downdetector is useful for early warning because it compares reports with typical volume for that time of day.[17] Treat it as supporting evidence beside OpenAI Status and your own tests.
What should I do if ChatGPT is stuck on generating?
OpenAI recommends waiting 30–60 seconds, clicking Stop generating, retrying with Regenerate, starting a new chat, hard refreshing, signing out and back in, and testing a private window or another network if the issue continues.[5] If OpenAI lists a matching degraded-performance incident, waiting is usually better than repeated retries.
Does a 429 error mean ChatGPT is down?
Usually no. A 429 or “too many requests” message normally means your account, browser session, or client is sending too many requests in a short period. It can happen during heavy use even when ChatGPT is otherwise available.